A third off the draw loop's CPU time by passing each draw's root arguments through the base instance
Under Rosetta, a Metal 4 draw costs twice as much when one buffer address changes before it. Handing each draw's offset to the shader as its base instance removed that address change, and bgfx's draw stress test went from 12.7 to 8.6 ms of CPU time per frame.
What changed
In D3D12, every draw can have its own root arguments: a few constants and buffer addresses that the shaders read. mtl12, my D3D12-on-Metal layer, put them in one buffer and set a new address in Metal's argument table before every draw. Last session's spike measured that change at roughly 100 ns per draw under Rosetta, which doubles the draw's cost.
This session removes it for most pipelines. The address stays fixed for the whole encoder. Each draw passes its block's offset as the base instance, which is the start value Metal adds to the instance index. The translated vertex shader reads the root arguments at base + 16 × base_instance. When the pixel shader needs them too, the vertex shader hands the offset over in a flat integer varying, which isn't interpolated. Some pipelines keep the old path:
- pipelines whose shaders or vertex data really use the start instance;
- tessellation and geometry shaders;
- a few rasterizer modes that mtl12 emulates with extra draws.
I wrote the test first: api/per_draw_root_args, 514 checks over every pixel of mixed draws. Breaking any one rule of the ADR fails it (chart below).
The interesting part
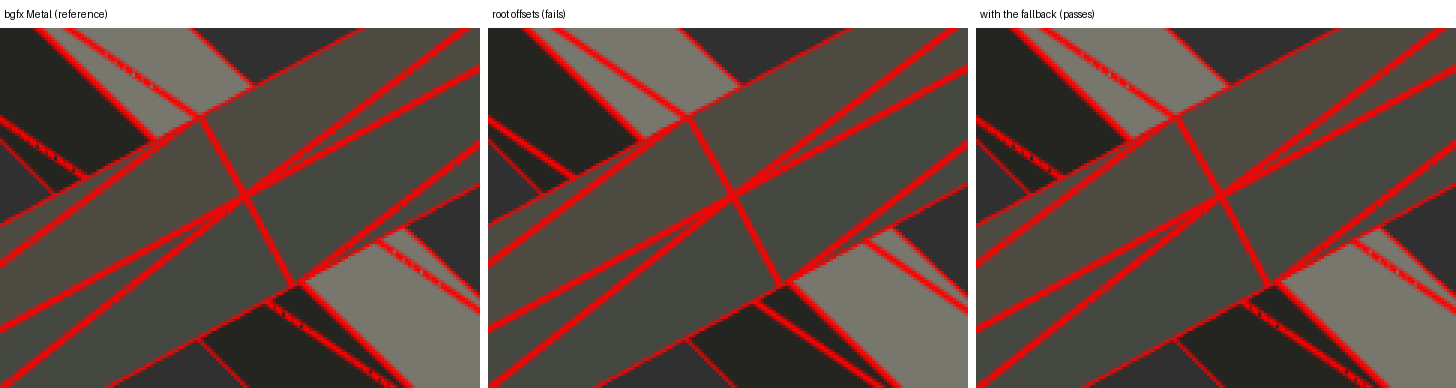
The full suite then found one regression the API test couldn't. bgfx's wireframe example draws its lines with fwidth (how fast a value changes between neighbouring pixels) inside a branch on a root constant. With root offsets, its thin lines came out continuous. bgfx's own Metal renderer, the test's reference, draws them broken. The new lines arguably look better, but they differ by 5684 pixels. bgfx's debug draw example failed too, by 387 pixels. I first took that for a known flaky test, but it fails every time with the fix below turned off.
My guess is that Metal's compiler computes derivatives differently once it can't prove the branch is the same for every pixel. I couldn't confirm it: a test with the same shape on affine barycentrics gets exact derivatives on both paths. So the rule is labelled as empirical in the ADR. A pixel shader that reads root arguments and takes explicit derivatives keeps the old path. That is 1 of 601 pipelines translated in the fast test subset, plus three in the debug draw example.
Numbers
- bgfx 17-drawstress, unix-side CPU per frame: 12.69 / 12.94 ms before, 8.61 / 8.64 ms after (two runs each). Frame time: 24.5 / 24.74 → 20.43 / 20.55 ms.
- bench-draws submit (the unix-side replay of the recorded draws): 2062 / 2065 → 1193 / 1216 µs.
- With no root bind at all, the spike's ceiling was 5.27 ms. The remaining 3.3 ms gap is unexplained.
- At the session's last commit, with the machine under other load (load average about 5): 9.18 / 8.95 ms unix CPU, 21.11 / 20.85 ms frame, bench-draws submit 1.20 ms in both runs. These are noisier than the earlier runs; I didn't isolate the 0.3-0.5 ms difference.
- Full suite at the session's end: 848 pass, 28 fail, 76 skip of 952, none newly failing.
build · failed checks
- as committed0
- offset draws always bind (slow but correct)0
- no per-instance-data fallback6
- no SV_StartInstanceLocation fallback4
- predicated draws keep start instance24
- predicated draws of every pipeline start at 04
- ExecuteIndirect keeps StartInstance14
- offset added twice74
- no location-49 fallback (pipeline fails; test stops)1
- no dxil-spirv patch 0005 (pipeline fails; test stops)1
- run 1
- run 2
build · unix CPU ms
- before12.69 run 1, 12.94 run 2
- offsets8.61 run 1, 8.64 run 2
- session end*9.18 run 1, 8.95 run 2
- no bind (spike)5.27 run 1, 0 run 2
- pass
- fail
- skip
suite · share of each row's total
- vkd3d-proton490 pass, 15 fail, 72 skip of 577
- vkd3d177 pass, 9 fail, 4 skip of 190
- api (+1)81 pass, 0 fail, 0 skip of 81
- apps (+1)80 pass, 0 fail, 0 skip of 80
- wine-dxgi16 pass, 4 fail, 0 skip of 20
- samples4 pass, 0 fail, 0 skip of 4